For two years now everyone has been told to optimise for ChatGPT without anyone really knowing what the machine goes looking for, or where. A study published in early August shifts that picture considerably, because it documents how the ChatGPT index actually works using observed data rather than guesswork. Some of it runs against the common wisdom, particularly around the role of Bing, around what triggers a citation, and around how your page gets stored once it has been read. After a year tracking AI search on my own sites, several of my working assumptions fell apart reading it. Here is what the mechanics mean in practice when you are starting out.
TL;DR
ChatGPT runs on its own index, separate from Google and Bing, returning a URL, a full title and a roughly 200-character snippet for each result.
A read cache shared across all users stores full pages converted to Markdown, working on a freshness window of about thirty minutes.
A page the model actually opens gets cited 74% of the time, against 7% for a page merely sitting in the index.
Over 90% of users stay on the free tier, meaning the mode that almost never opens pages: being well indexed matters as much as being well written.
Summarize This Article with AI
ChatGPTThe ChatGPT Index Is Not Fed by Bing
Start with the finding that upends the most habits. ChatGPT was long assumed to lean on Bing for its web searches, which pushed plenty of beginners to prioritise Bing Webmaster Tools. The data does not support that reading.
The research led by Olivier De Segonzac, founder of Resoneo, rests on 1,249 captured responses, 88,000 search results, 26,900 distinct pages and 6,400 domains, across free and paid accounts in several countries. The full method and the raw observations sit in the published study of the ChatGPT retrieval stack.
That internal index carries a codename, labrador, and it operates on its own. Measured overlap with the top twenty Bing results drops to 1.5%, which rules out the idea of a simple Bing passthrough fairly cleanly.
Every result the index returns holds three things: the page address, the untruncated title, and a snippet of roughly 200 characters anchored to the H1 content. That last detail changes your editorial work directly. The snippet ignores the meta description, and it ignores the question asked, which means the same snippet is served whatever the original query. No contextual rewriting happens the way a Google snippet adapts.
The crawler feeding that store identifies itself as OAI-SearchBot in server logs. A second one, ChatGPT-User, works on an entirely different layer, while a third, GPTBot, handles model training without appearing in either mechanism.
That three-crawler split is worth holding onto, because it settles a confusion that trips up plenty of beginners. Blocking GPTBot to refuse model training does not pull you out of the ChatGPT index, since a different crawler handles that job entirely. A lot of sites made that call believing they were going invisible, or fearing they would vanish, when the two mechanisms stay separate on OpenAI’s side.
For a sense of scale, the ChatGPT index observed here spans 6,400 domains across the analysed corpus, which stays modest next to what a conventional search engine sweeps. The practical read is fairly encouraging when you are starting out: competition to appear there is far thinner than on Google, and a young site is not automatically pushed behind the established media names. That density swings hard from one field to the next, which goes a long way toward explaining why ChatGPT citations depend so much on your topic.
The Read Cache and Its Thirty-Minute Window
The second layer is the one most coverage skips over, even though it explains a lot of observed behaviour. When ChatGPT genuinely opens a page, it does not re-read it live for every conversation. It converts the page to Markdown and files it in a read cache.
That cache is shared across all users, keyed on nothing more than the page address. If someone had your article opened minutes earlier, the next user gets the cached version. The observed freshness window runs around thirty minutes, with a background refresh once it lapses. Retention stretches much further, with documented cases beyond ninety days.
Two technical limits deserve your attention. Weight comes first: past four megabytes a page is not read at all, and the rejection is total rather than partial. JavaScript comes second, since it is not executed. Anything rendered browser-side stays invisible, which hits sites that load their main text after the initial render particularly hard.
Both constraints push plain technical fundamentals back to the front, after a year of GEO advice burying them under fashionable recipes. A heavy or JavaScript-rendered page drops out before it is ever assessed, however good the writing behind it. The same logic already made structured data less decisive than advertised, something I dug into when checking whether schema markup really gets read by AI.
Sharing the cache between users carries another implication, a more reassuring one. You do not need the model to re-read your page for every conversation to stay in play, since a single read then serves everyone for the current window. In practice that means a substantial content update takes a while to circulate, which argues for getting a page right at publication rather than tinkering with it continuously.
One simple check tells you where you stand without any paid tool. Open your hosting access logs and search for the three names above. OAI-SearchBot showing up means you are being crawled for the ChatGPT index, while ChatGPT-User means your pages are genuinely being opened and cached. Neither appearing at all is the real warning sign, well ahead of any editorial quality question.
What Separates a Listed Page From a Cited One
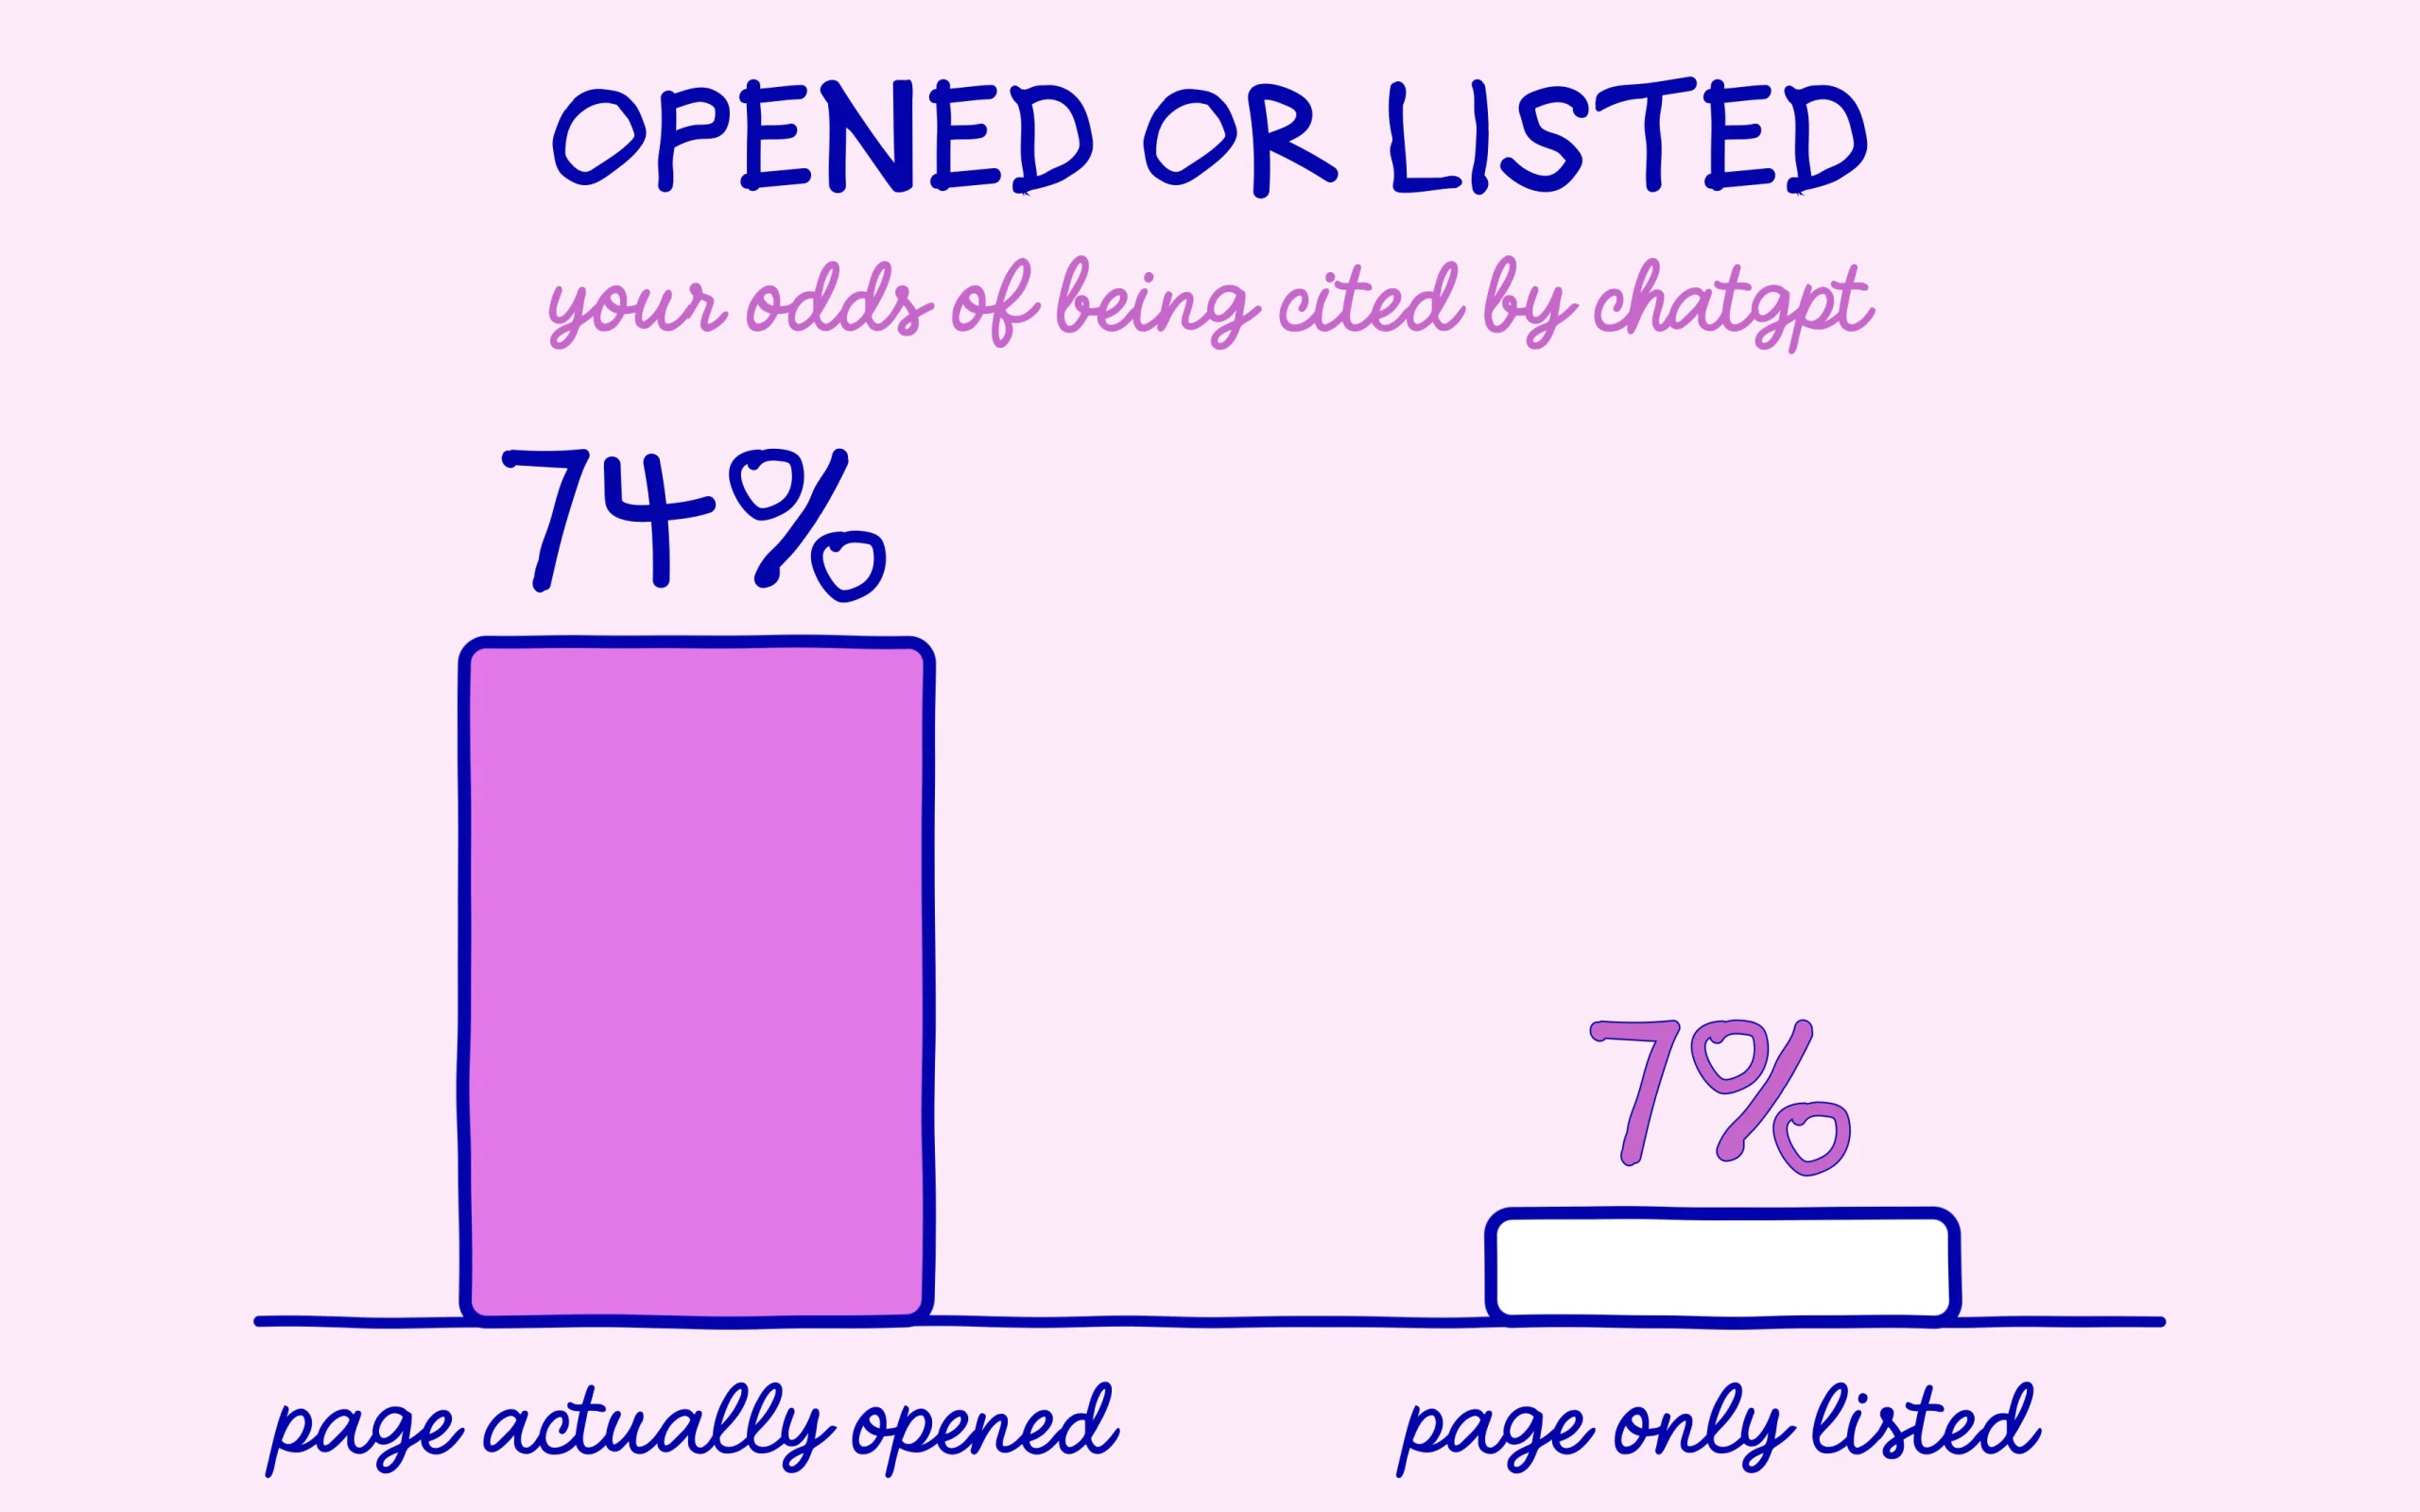
The most telling number in the whole study fits in one comparison. A page the model genuinely opens ends up cited in 74% of cases. A page that merely surfaces in the index results, without being opened, drops to 7%.
That gap is enormous, and it moves the question elsewhere. Sitting in the index puts you in the waiting room. Being opened puts you at the table. Except opening depends mostly on the mode in play: of 759 opened pages recorded, 757 came from thinking mode, which paid accounts get.
And over 90% of ChatGPT users stay on the free tier, so on the instant mode that leans almost entirely on the index. For the vast majority of conversations touching your sector, your page never gets opened. What circulates is your title and your 200-character snippet.
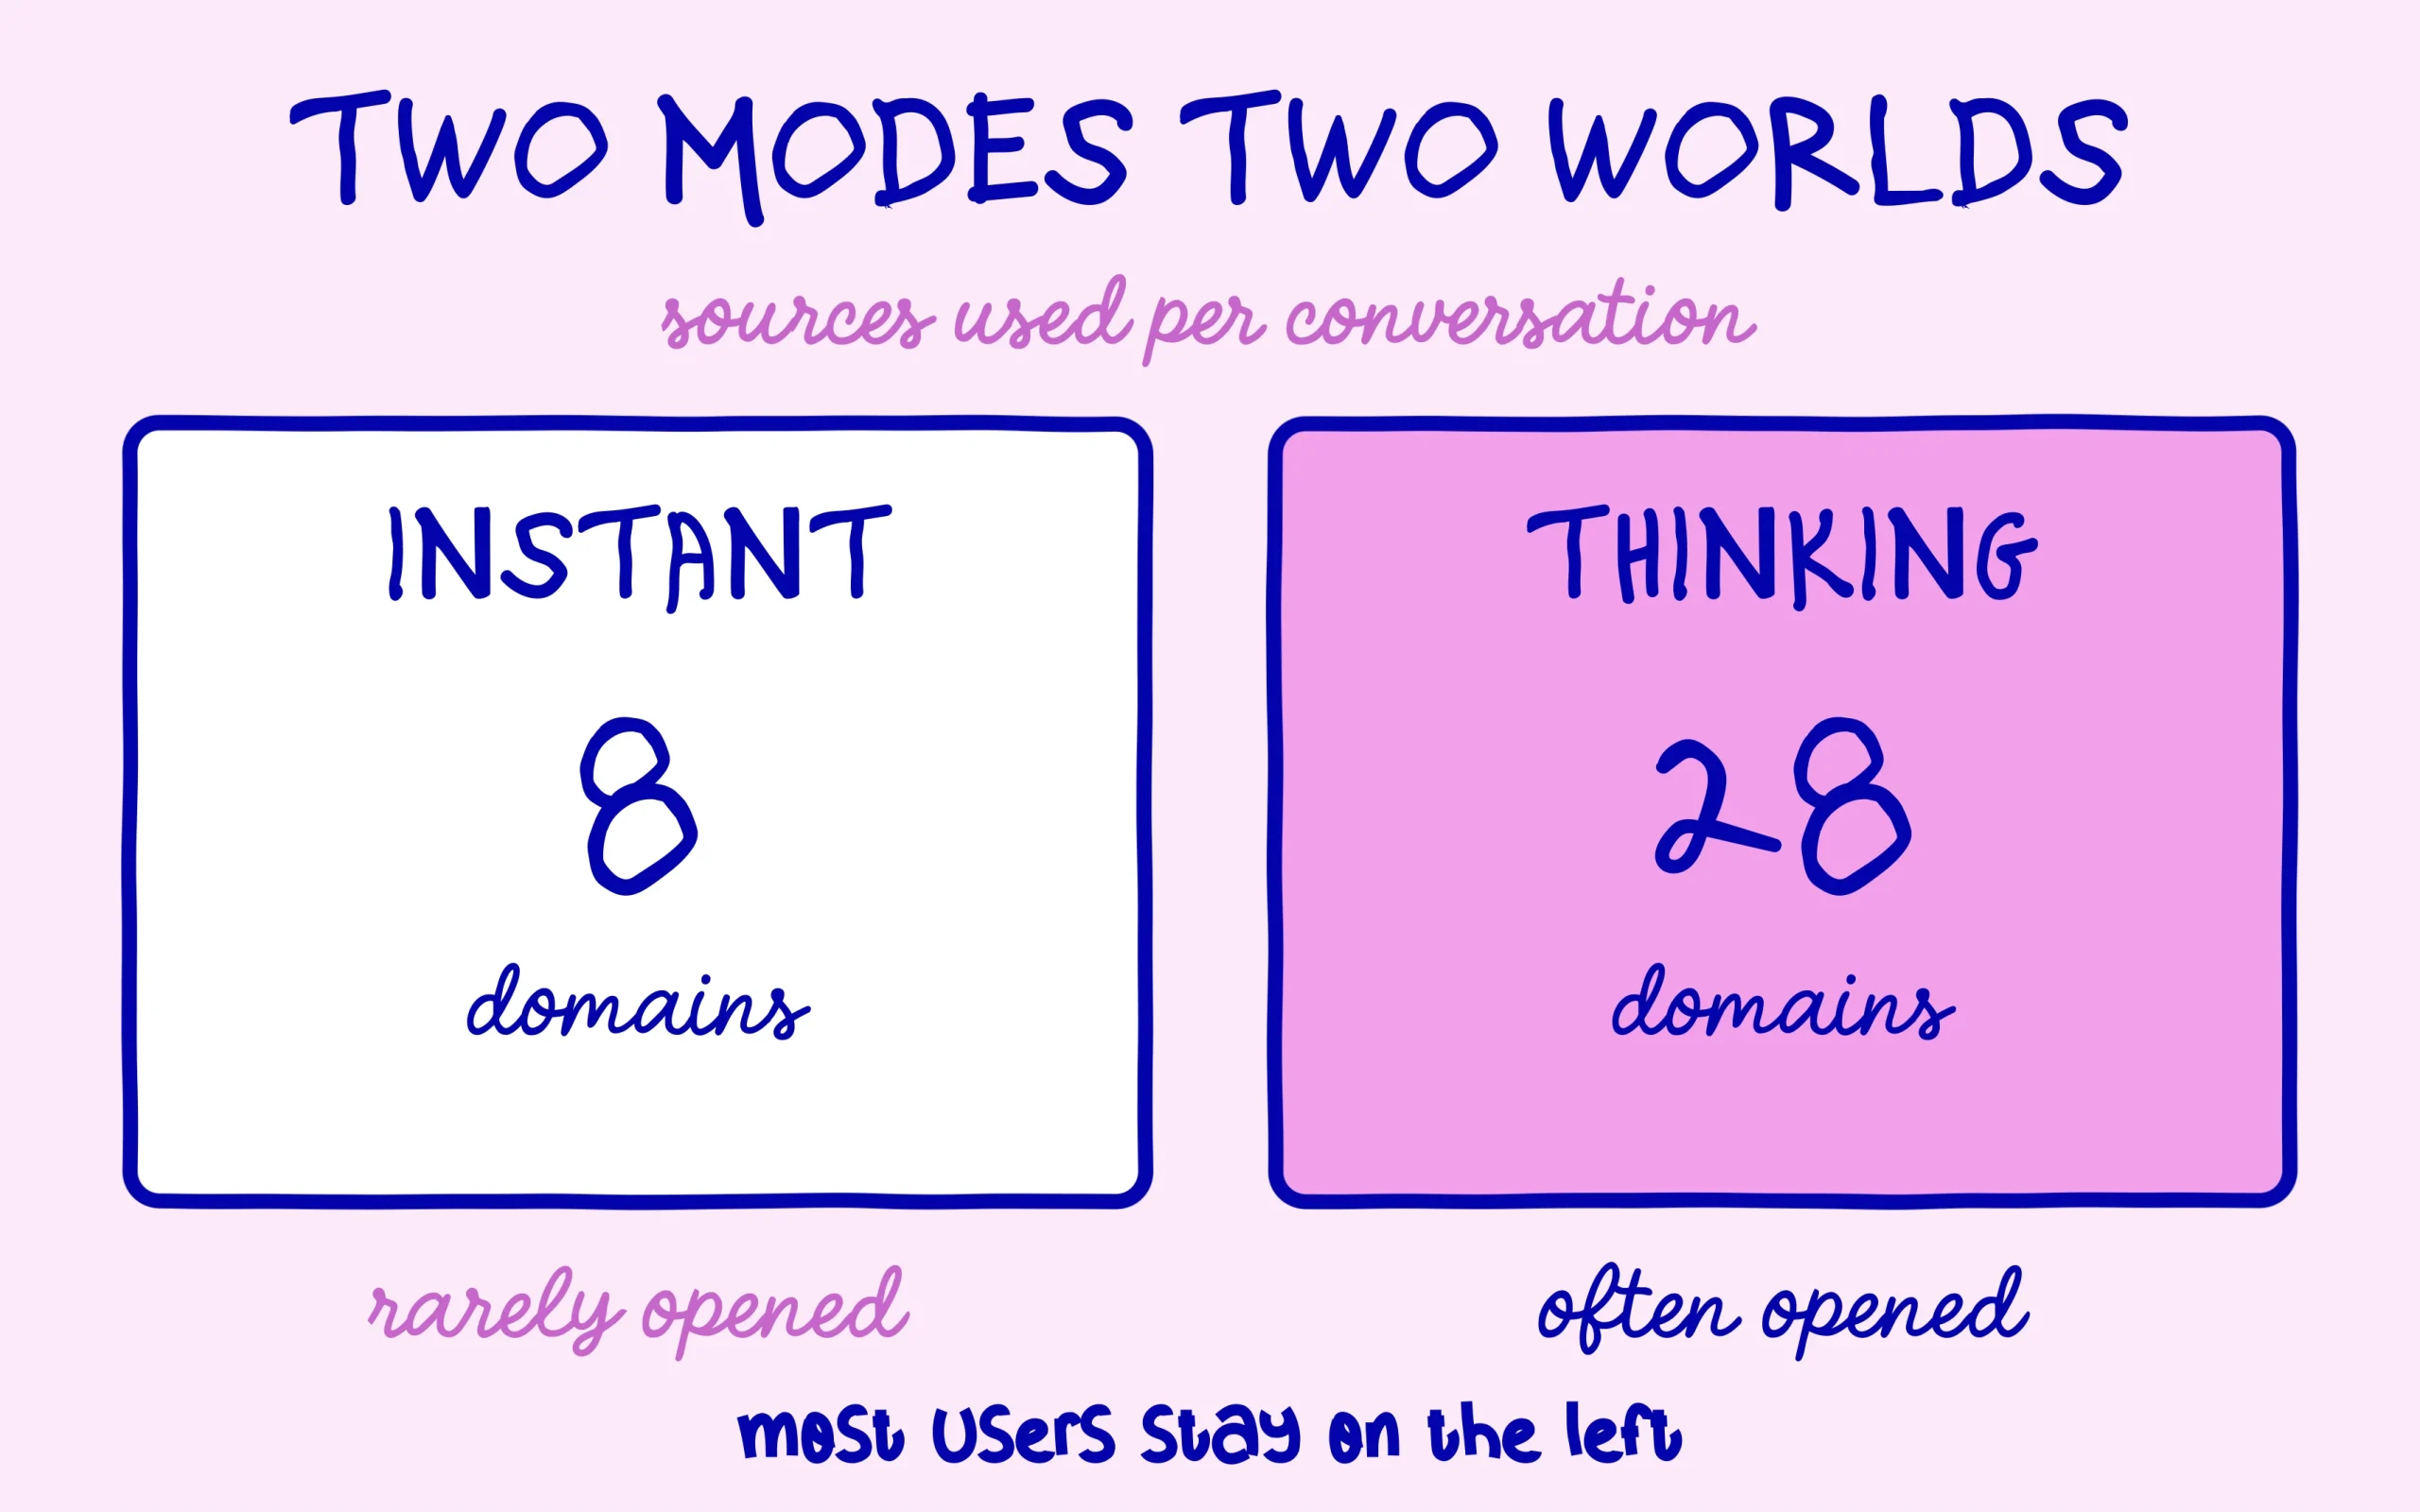
Source counts split along the same line. Instant mode draws on a median of eight distinct domains per conversation, where thinking mode pulls in twenty-eight. The first leaves very few seats, and it hands them out on the strength of title and snippet alone.
Turned into action, that gives a beginner one clear priority to work on this week. Pull up your ten most strategic pages and re-read nothing but the H1 and the opening paragraph, asking whether those two hundred characters make it obvious what the page covers and who it serves. A clever but opaque title costs you dearly in the ChatGPT index, precisely because no query context will ever fill the gaps.
My reading after this study is reasonably simple to state. The useful work starts with the H1 and the opening lines, since those feed the frozen snippet that will represent you in most answers. Depth and reliability come next, mattering once a page actually gets opened. Fields where few sites handle both layers properly therefore leave plenty of room for newcomers, and that window will not stay open indefinitely.
There is a second, quieter consequence for anyone weighing where to spend their time. Since the snippet gets frozen at crawl time and ignores the question asked, the usual advice about matching content to search intent loses some of its grip inside the ChatGPT index. What earns you a seat is a page that states plainly what it covers, not one tuned to a specific phrasing someone might type. Clarity beats keyword gymnastics here, which is a rather welcome shift.
Worth adding that none of this replaces ordinary search work. The same pages that load fast, render server-side and carry a clear H1 also perform better on Google, so the effort compounds rather than splitting in two directions. Anyone being told they need a separate strategy for AI search is, in my experience, selling something.
I could be wrong on the timing, and these mechanics will very likely shift over the coming months. That said, the direction looks stable enough: the model favours sources it keeps meeting on the same ground over one well-optimised isolated page, which lines up with what we already saw around topical authority and the references AI cites. Publishing steadily on a defined subject still pays better than chasing the latest technical trick.
Keep learning on SEO Noobies.
[…] cutting mechanic matches what we unpacked about how the ChatGPT index picks the pages it cites. The engine hunts for passages that stand on their own legs, with something checkable inside. A […]
[…] index carries an internal codename, Labrador. Its existence was already documented, and we covered how the ChatGPT index picks the pages it cites. What the new analysis adds is the shape of it. Instead of one enormous store of pages, there is a […]
[…] relevant, contract or no contract, through selection mechanics we broke down in our article on how the ChatGPT index picks the pages it cites. Paying a publisher does not make it citable everywhere, which is decent news for everyone with […]